Adding Shapes: My Bachelor Thesis on Minkowski Sums
Table of Contents
On 15 July 2019 I handed in my bachelor thesis, Berechnung der Minkowski-Summe für einfache Polygone (Calculating the Minkowski Sum of Simple Polygons). It is a fairly mathematical document, but the problem it solves has an appealingly physical interpretation: what shape do you get when you slide one shape over another and collect every position it can reach?
This post is the version I wish I had written alongside the thesis. It focuses on the central idea rather than reproducing all of the definitions, proofs, and implementation details.
The shape made by adding every point #
For two sets of points A and B in the plane, the Minkowski sum is
A ⊕ B = {a + b | a ∈ A, b ∈ B}
The addition is vector addition. Pick one point from each shape, add their coordinates, and the resulting point belongs to the sum. Repeating that for every pair fills the result.
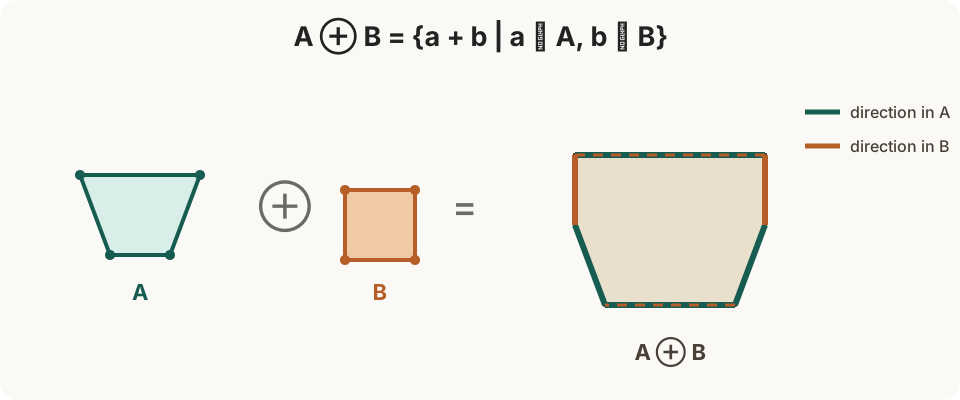
That definition is simple, but implementing it is not. There are infinitely many pairs of points, and even the finite set of polygon vertices does not tell us the whole answer by itself. The useful observation is that the boundary carries enough structure to construct the result.
This operation appears in places where geometry and algorithms meet:
- In motion planning, a robot restricted to translation can be replaced by a reference point. For an obstacle O and robot shape R, the forbidden positions of that point form O ⊕ (−R), where −R is the robot reflected about its reference point.
- In CNC and 3D printing, offset geometry by the tool or nozzle footprint to derive paths for its reference point.
- In collision detection and image processing, use the same operation as a geometric form of dilation.
The easy case: convex polygons #
For two convex polygons, there are two natural algorithms.
The straightforward one forms every vertex sum vᵢ + wⱼ, then computes the convex hull. With n and m vertices, this creates n · m candidates before the hull algorithm removes the ones that cannot be on the boundary.
The better algorithm exploits the fact that the edges of a counterclockwise convex polygon are already cyclically ordered by direction. In the thesis’s formulation, start at the lexicographically smallest vertex by x and then y in each polygon, and add these two starting vertices. Then merge the two edge sequences by polar angle. At every step, append the next vertex sum after advancing along the edge with the smaller angle. If both edges point in the same direction, advance in both polygons. The resulting edge is the sum of the two edge vectors. Every input edge is consumed exactly once, so the running time is O(n + m).
This is a small but important algorithmic lesson: the geometry gives us an ordering for free. Once we use it, we no longer need to generate and sort all possible vertex pairs.
Why concave polygons change everything #
Concavity breaks that one-pass walk. The sum of two concave polygons may have indentations, several boundary components in intermediate constructions, and edges that overlap or intersect. A local choice of the next edge is no longer enough to tell us which parts will survive in the final boundary.
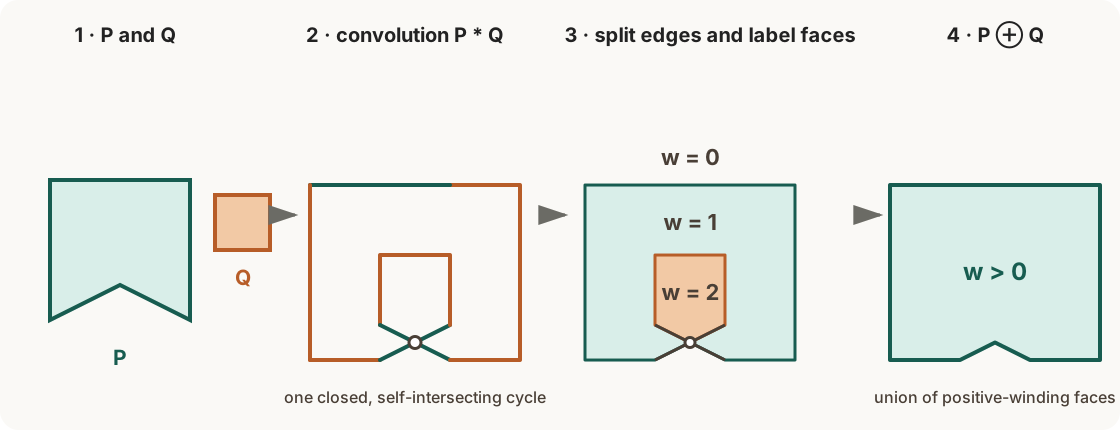
The main part of my thesis therefore uses the convolution method. Its essence is to construct a deliberately redundant arrangement first, and only then decide which parts belong to the Minkowski sum.
The algorithm in three ideas #
1. Translate edges by vertices #
Assume that both polygon boundaries are oriented counterclockwise. For an oriented edge pᵢpᵢ₊₁ of polygon P and a vertex qⱼ of polygon Q, translate the edge by that vertex. This produces the segment [pᵢ + qⱼ, pᵢ₊₁ + qⱼ]. The segment is included only when the edge direction lies in the angular interval swept by the two incident edges at qⱼ. The construction is repeated symmetrically for every edge of Q and matching vertex of P.
The selected edge-vertex translations form the convolution. Its segments join into closed curves, but those curves need not be simple. If at least one input polygon is convex, the thesis’s algorithm produces one convolution cycle. Two concave polygons may require several cycles. They are candidates for the answer’s boundary and may cross one another or enclose regions that should not be included.
A single convolution cycle contains at most O(nm) segments. Constructing all required cycles for two concave polygons takes O(n² · m²) time in the algorithm presented in the thesis.
2. Turn segments into a planar data structure #
The segments are split wherever they intersect and stored in a doubly connected edge list (DCEL). A DCEL records vertices, directed half-edges, their twins, the next edge around a face, and the face each edge bounds.
This data structure is the bridge between geometry and topology. Instead of asking complicated questions about every point, we can walk around each face of the arrangement and reason about its boundary. The implementation also has to handle coincident or overlapping segments. This unglamorous detail becomes central when coordinates are represented by Java doubles.
3. Use winding numbers to select the result #
The convolution describes more than the Minkowski sum. The final step is a classification problem. For each face, the algorithm computes its winding number: informally, how many times the oriented convolution winds around a point in that face.
Faces with a positive winding number are the regions belonging to P ⊕ Q. Equivalently, the implementation follows the half-edges beside the unbounded face to obtain the outer boundary, then treats bounded zero-winding faces as holes. A face with winding number two is still part of the result, not a hole. In other words, the algorithm does not try to guess the final boundary while constructing it. It constructs all plausible boundaries, labels the regions, and filters the arrangement using a topological invariant.
That separation is the central idea of the thesis:
Geometry proposes the edges. Topology decides which regions survive.
What made the implementation difficult #
The mathematical description is neat. The code is where the edge cases live.
I implemented and tested the algorithms in Java 8 using the ADSToolbox framework from the University of Bayreuth.
From rounding to explicit comparison rules #
The existence of floating-point rounding errors was not surprising. What surprised me was how quickly a tiny numerical difference could become a topological error. If three segments should meet at one point but the calculations produce two almost identical points, the DCEL no longer sees one shared vertex. Half-edges can remain disconnected, faces may not close, and winding numbers can become wrong.
Exact equality between calculated double values is therefore usually the wrong question. The thesis implementation addressed this defensively. It first attempted the calculation without rounding. If the DCEL consistency checks failed, it retried with progressively coarser decimal rounding, down to four decimal places. I also considered BigDecimal, but adapting the surrounding double-based framework was beyond the scope of the thesis.
I later explored this problem more deliberately in my open source Kotlin Multiplatform library, Komp-Geom. Instead of scattering direct comparisons and arbitrary tolerances throughout the algorithms, the library represents the comparison policy with a DoubleEquivalence interface. Its default implementation considers two values equivalent when
|a − b| ≤ ε · max(1, |a|, |b|)
with a default ε = 10⁻¹⁰. Near zero, this behaves like an absolute tolerance. For larger values, it scales with their magnitude. The same policy provides equality, zero, and ordering operations, and geometric operations can receive a different equivalence when their scale or requirements differ.
This is a better design than hiding raw == checks throughout a geometry library, but it is not a universal cure. Approximate equality depends on the scale and purpose of a calculation, and it is not transitive in the mathematical sense. Algorithms that require stronger guarantees may need exact or adaptive geometric predicates. The important lesson for me is that number comparison belongs in the algorithm’s design and API, not in a last-minute collection of special cases.
Some other practical lessons from the thesis have also stayed with me:
- Normalize inputs early. Consistent orientation and removing redundant vertices simplify every later step.
- Avoid redundant objects. The convolution can grow quickly, so unnecessary allocations and repeated calculations become expensive.
- Choose data structures for the access pattern. In one part of the algorithm, random access to a sequence is important. A linked list would quietly turn a linear operation into a quadratic one.
- Test topology, not only coordinates. In addition to hand-computed JUnit cases, the implementation checked that every half-edge had a predecessor and successor, each face boundary was a simple polygon, and every boundary edge implied the same winding number for its face.
The convolution method’s running time is bounded by O(n² · m²) for two simple polygons. Both the construction of all convolution cycles for two concave inputs and the worst-case DCEL have this bound in the thesis. The experiments also show why the arrangement dominates in practice. In one example, the DCEL contained 5,794 half-edges, while only 27 of them formed the outer boundary of the result. It is not the last word in Minkowski-sum algorithms, but it is a general method for the non-convex case considered in the thesis.
Looking back #
What I like about this project is that the final shape is the visible result of several layers of reasoning: vector addition, edge orientation, planar subdivisions, and winding numbers. None of those ideas is sufficient on its own. Together they turn a continuous geometric definition into a finite algorithm.
The obvious next step, which I identified in the thesis, is a reduced convolution. It omits segments generated by reflex vertices when those segments cannot contribute to the boundary. This produces fewer intersections and less bookkeeping, but it also breaks the closed convolution cycles, so winding numbers alone can no longer classify the result. Additional geometric filters are needed instead. Implementing and comparing that trade-off would be a natural follow-up project.
Writing this down years later also makes the broader lesson clearer: when a direct construction becomes messy, it can be more effective to build a rich intermediate representation and extract the answer from it with the right invariant.